Beyond the Hype: A Practical Guide to Integrating AI into Your Development Workflow
The conversation around AI in software development has spent several years oscillating between two extremes. One side presents generative AI as the beginning of autonomous software engineering, while the other focuses on hallucinations, unreliable code, security risks, and the possibility that developers will eventually spend more time correcting AI than benefiting from it.
Neither extreme is particularly useful for a development team deciding what to do on Monday morning.
AI adoption is already widespread. In Stack Overflow's 2025 Developer Survey, 84% of respondents said they were using or planning to use AI tools in their development process, and 51% of professional developers reported using them daily. At the same time, trust has not grown at the same rate. More developers said they distrusted the accuracy of AI output than trusted it, while 66% identified solutions that were "almost right" as their biggest frustration with AI tools.
That gap between adoption and trust captures the real engineering challenge.
The question is no longer whether development teams should experiment with AI. The more useful question is how AI should be incorporated into an engineering system where generated code still needs to satisfy architecture standards, security requirements, tests, performance constraints, documentation conventions, and business requirements.
Modern AI development tools are also moving far beyond autocomplete. Coding agents can inspect repositories, modify several files, execute commands, run tests, investigate failures, and prepare pull requests. GitHub's current agent workflow, for example, allows an agent to work on a task and return a pull request for human review, while OpenAI describes coding agents that can move from an issue to tested, review-ready code.
This changes the role AI can play inside the development lifecycle, but it also changes the risk model.
A system that suggests the next line of code requires one level of trust. An agent that can edit a repository, install dependencies, access the network, execute commands, or interact with infrastructure requires something much closer to an operational security model.
The most useful AI development workflow is therefore neither "let AI write everything" nor "use AI only as autocomplete." It is a layered approach in which the amount of autonomy increases together with context, validation, security controls, and human oversight.
AI in Software Development Is Moving From Assistance to Execution
The earliest mainstream coding assistants operated primarily at the level of individual lines and functions. A developer began writing code, and the model predicted what should come next.
That interaction still exists, but the surrounding workflow has changed substantially.
Modern development assistants can operate with repository context rather than a single source file. They can explain unfamiliar modules, locate related code, suggest refactoring across several files, generate tests, analyze a pull request, and in increasingly agentic environments perform a sequence of development operations rather than producing one isolated answer.
GitHub, for example, now describes Copilot code review as using project context to provide more specific reviews and allowing suggested fixes to be passed to a cloud agent. OpenAI similarly describes coding agents that can plan changes, write code, run tests, prepare pull requests, debug issues, perform refactors, and assist with migrations while engineers retain control over what ultimately ships.
This distinction matters because the value of AI changes as its context expands.
An autocomplete system primarily saves keystrokes. An assistant with repository context can save investigation time. An agent capable of using development tools can remove entire sequences of mechanical work.
The progression can therefore be understood as a movement from generation toward execution, with human engineering judgment remaining responsible for defining the objective and validating the result.
Start With the Work Developers Already Repeat
The most practical way to integrate AI into a development process is not to begin with autonomy. It is to identify tasks where developers repeatedly spend time producing predictable output.
Boilerplate code is an obvious example, but the category is much broader. Developers routinely create test fixtures, translate requirements into initial implementations, write repetitive validation logic, produce documentation, explain existing code to colleagues, investigate unfamiliar APIs, prepare migration scripts, refactor similar structures, and summarize changes for pull requests.
These tasks are useful candidates because the output can usually be inspected relatively quickly.
A generated database migration that changes critical production data is a different risk category from a generated test fixture. An AI-generated authentication flow deserves more scrutiny than documentation for an internal helper function.
This suggests a simple principle for adoption: the lower the cost of verifying the output and the lower the impact of failure, the easier the task is to delegate.
AI integration should therefore begin with verification economics rather than novelty.
The IDE Is Still the Simplest Entry Point
For many teams, the first meaningful AI integration remains the development environment itself.
A coding assistant can use the code surrounding the developer's current position to propose an implementation, complete repetitive structures, draft unit tests, or explain unfamiliar logic. When the developer remains actively involved in writing and reviewing the code, AI functions primarily as an acceleration layer rather than an autonomous contributor.
The quality of this interaction depends heavily on context.
A vague instruction such as "add validation" forces the model to infer what validation means. An instruction that specifies the accepted values, error behavior, existing project conventions, and relevant edge cases gives the model a much narrower problem to solve.
The same principle applies at larger scales. AI performs more reliably when it knows what the component is supposed to do, what constraints apply, which conventions the repository follows, and what a valid result looks like.
This is why effective AI-assisted development increasingly depends less on clever prompt phrasing and more on providing reliable engineering context.
Integrate AI Without Disrupting Development
Start today with usRepository Context Is More Valuable Than a Clever Prompt
A model can generate syntactically correct code while still producing a completely inappropriate implementation for a particular system.
It may choose a library the organization does not use, reproduce functionality that already exists elsewhere in the repository, violate an internal architectural boundary, introduce a new convention unnecessarily, or solve the local problem while creating a maintenance issue elsewhere.
The missing ingredient is often not model intelligence but context.
Repository-level AI tools reduce this problem by allowing the model to inspect related source files, tests, configuration, documentation, and architectural patterns before proposing a change. GitHub's current code review capabilities, for example, can gather broader project context when reviewing code rather than evaluating only an isolated diff.
Teams can improve this further by making their engineering knowledge machine-readable. Coding conventions, architecture decisions, testing requirements, security expectations, dependency policies, and definitions of done should not exist only in the memories of senior engineers.
The more explicit the engineering environment becomes, the more useful AI can become inside it.
This creates an interesting secondary effect: organizations attempting to adopt AI often discover weaknesses in their own documentation and development processes. If an AI agent cannot determine how a service should be tested, deployed, or structured because the relevant rules exist nowhere outside team conversations, a new developer may have exactly the same problem.
AI Can Support Much More Than Code Generation
Treating AI exclusively as a code generator significantly underuses the technology.
Software development includes large amounts of work that surrounds implementation. Engineers need to understand requirements, investigate existing systems, compare possible approaches, create tests, review changes, diagnose failures, update documentation, and understand what happened when something breaks in production.
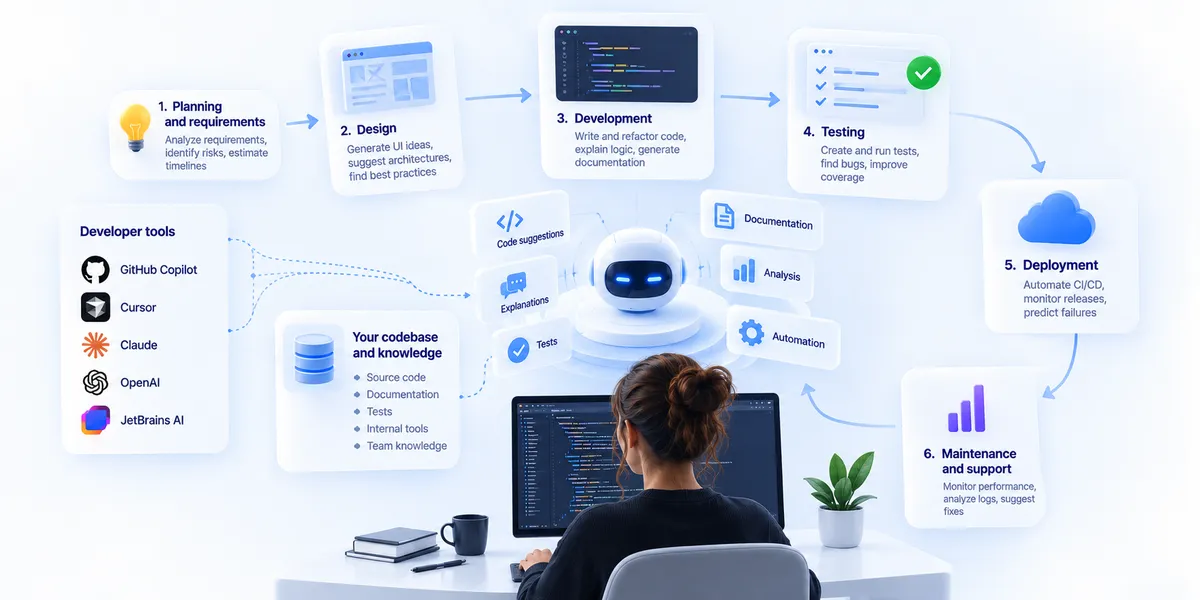
The second source provided for this article makes the same broader point by describing AI applications across planning, design, development, testing, deployment, and maintenance rather than restricting AI to the coding phase.
In practice, some of the safest productivity gains may occur outside direct code generation.
An AI assistant can summarize an unfamiliar module before a developer modifies it, explain a stack trace, compare an implementation against acceptance criteria, generate candidate test scenarios, identify areas of a change that deserve additional review, or turn a large collection of technical information into a starting point for investigation.
These activities accelerate understanding without necessarily giving the AI authority to change the system.
Testing Is One of the Strongest AI-Assisted Use Cases
Testing is particularly well suited to AI because much of the work combines structured reasoning with repetitive implementation.
Given a function, API contract, user story, or existing test suite, an AI system can propose missing scenarios, generate test skeletons, identify boundary conditions, create representative input data, and suggest failure cases that may not have been included in the original implementation.
This does not mean that AI should determine whether the product has been adequately tested.
Generated tests can reproduce the same incorrect assumptions as generated code. If the model misunderstands a requirement, it may generate an implementation and then create tests that successfully confirm its own misunderstanding.
The more robust pattern separates implementation from validation. Requirements and acceptance criteria remain an independent source of truth, while AI can accelerate the translation of those requirements into executable tests.
For QA teams, this distinction is particularly important. AI can increase the number of test ideas generated quickly, but coverage is not the same as quality. Risk assessment, business criticality, production behavior, user expectations, and the probability and impact of failure still require human judgment.
AI Code Review Works Best as Another Review Layer
AI-assisted code review is also becoming a practical part of the development workflow.
GitHub currently allows Copilot to review pull requests, identify potential issues, suggest changes, and use broader repository context during the review. Organizations can also provide repository-specific instructions and connect additional context through agent skills and MCP servers.
This makes AI useful as an additional review pass before or alongside human review.
The distinction between additional and replacement is important.
AI can identify suspicious patterns, missing error handling, inconsistencies, potential bugs, or code that deserves closer inspection. Human reviewers still need to evaluate whether the change solves the right business problem, fits the architecture, introduces acceptable tradeoffs, and behaves correctly in situations that may not be visible from the code itself.
A useful workflow therefore treats AI review similarly to static analysis or automated testing. It expands the number of signals available to the reviewer without transferring final engineering accountability to the tool.
Documentation Is a Natural Candidate for Automation
Documentation is another area where AI can remove substantial mechanical work.
Developers frequently postpone documentation because implementation work takes priority, and documentation gradually becomes disconnected from the system it describes. AI can help draft API descriptions, summarize modules, generate docstrings, explain configuration, prepare release notes, and identify obvious differences between documentation and implementation.
Agentic workflows make this more interesting because the task can become continuous rather than reactive. An agent with appropriate repository access can compare changed code against existing documentation and propose updates when the two diverge.
The developer then reviews the documentation change together with the code that caused it.
This does not solve every documentation problem because AI cannot determine which undocumented architectural knowledge exists only in a developer's head. It can, however, substantially reduce the amount of repetitive writing required to keep technical documentation synchronized with observable system behavior.
AI Agents Change the Workflow More Than Code Assistants Do
The transition from assistant to agent is one of the most significant changes in AI-assisted development.
A traditional assistant responds to a request. An agent can interpret a goal, inspect available information, choose tools, perform actions, evaluate results, and continue working until it reaches a completion condition or requires human intervention.
The supplied expert article describes this as extending AI from information into execution, where the model orchestrates existing engineering systems rather than replacing them.
For software development, this can mean receiving an issue, examining the relevant repository, locating affected files, implementing a change, running tests, correcting failures, and preparing a pull request.
Current tooling already supports versions of this workflow. GitHub's Copilot agent can work on tasks and return pull requests for developer review, while OpenAI describes Codex workflows that move from issues to tested code prepared for review.
The productivity opportunity is substantial because developers no longer need to perform every mechanical step themselves.
The security implications are equally substantial because the AI is no longer merely generating text.
More Autonomy Requires Stronger Boundaries
A coding agent may be able to read source code, modify files, execute shell commands, install dependencies, access external services, interact with repositories, and potentially reach infrastructure.
OWASP's current secure coding guidance specifically addresses this new class of risk, noting that agentic coding tools can perform actions such as editing files, executing commands, accessing networks, and pushing branches.
This means AI permissions should be designed according to the same principle of least privilege that applies elsewhere in security engineering.
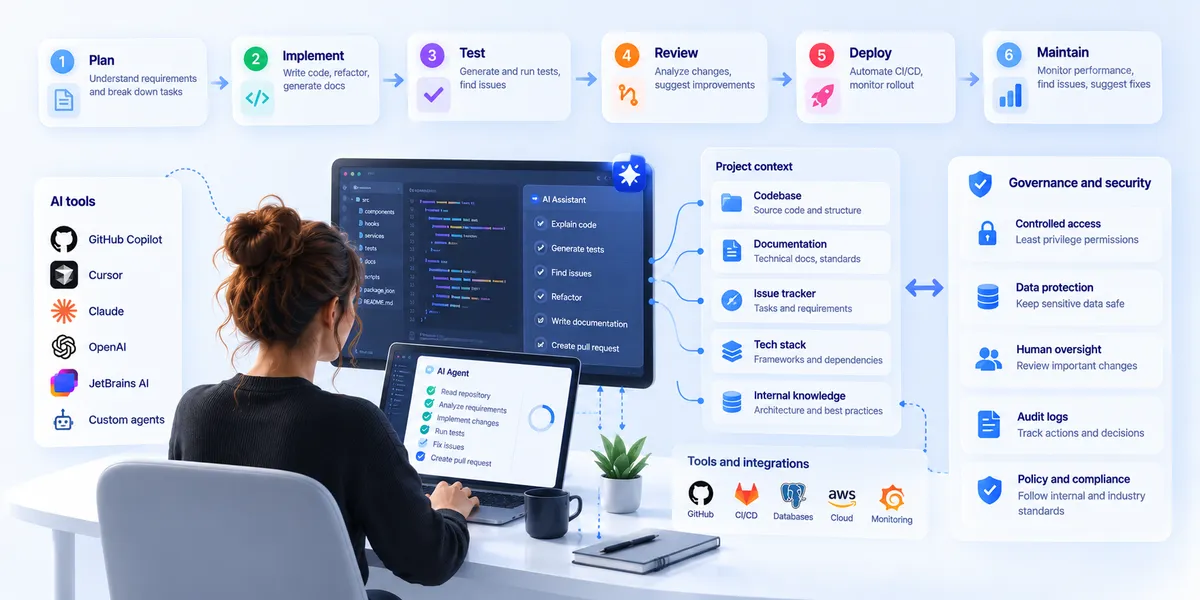
An agent working on frontend tests probably does not need production database credentials. An agent investigating a build should not automatically receive unrestricted infrastructure permissions. Network access should be constrained when it is unnecessary, while sensitive operations should require explicit approval.
OpenAI describes a similar model for internal Codex deployment, combining sandboxing, network controls, approval requirements, and agent-specific telemetry so that low-risk actions can proceed while higher-risk operations cross explicit control boundaries.
The more capable the agent becomes, the less appropriate unrestricted "auto-accept everything" behavior becomes.
Automate More Without Losing Engineering Control
Talk to our expertsHuman Review Becomes More Important as AI Generates More Code
One of the paradoxes of AI-assisted development is that faster code generation can increase the importance of review.
When implementation becomes cheaper, teams can produce larger volumes of code and more frequent changes. That can move the bottleneck from writing software toward understanding, validating, integrating, and maintaining it.
DORA's research provides an important warning here. Its research on generative AI found that greater AI adoption did not automatically translate into better software delivery performance. In one analysis, a 25% increase in AI adoption was associated with a 1.5% decrease in delivery throughput and a 7.2% decrease in delivery stability, with larger change batches identified as one possible mechanism.
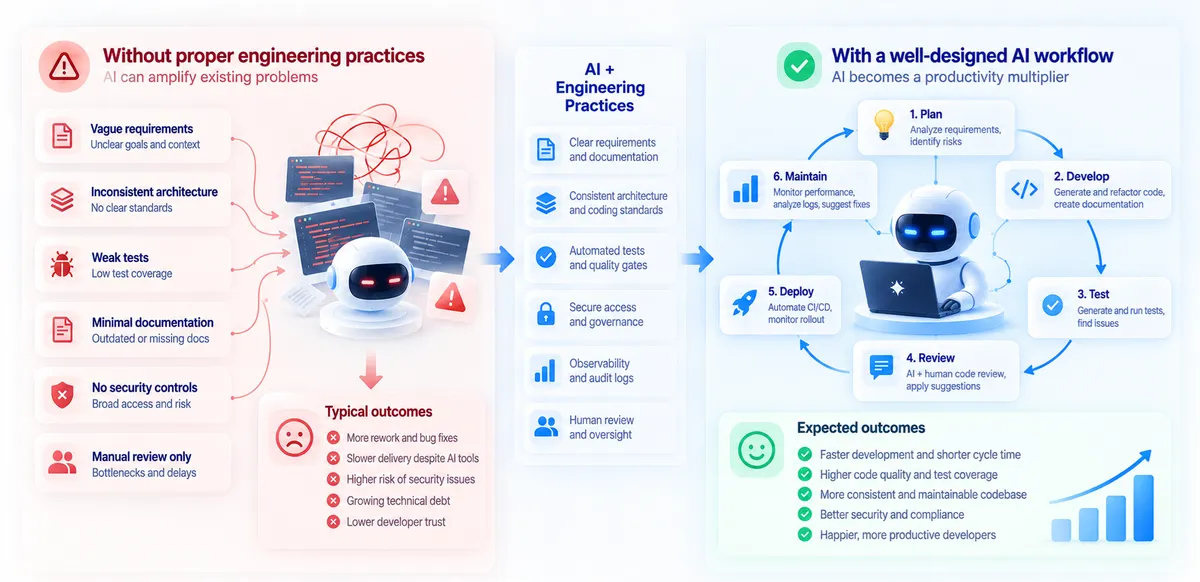
The more recent 2025 DORA research frames AI as an amplifier of the organization around it. Strong engineering systems can obtain greater value from AI, while existing organizational weaknesses can also be amplified.
This is a much more useful mental model than assuming that AI automatically creates productivity.
A team with weak tests, inconsistent architecture, poor documentation, and slow review does not necessarily become efficient because it can generate code faster. It may simply produce questionable code faster.
Developer Productivity Is More Complicated Than Lines of Code
AI productivity claims should also be interpreted carefully because software engineering productivity is difficult to reduce to a single metric.
Developers often report that AI makes them faster. DORA has found substantial self-reported productivity benefits, and Stack Overflow's 2025 survey found that 52% of developers agreed that AI tools or agents had positively affected their productivity. Among developers already using agents, reported productivity improvements were considerably stronger.
However, controlled research has produced more nuanced results.
A 2025 randomized controlled trial from METR studied experienced open-source developers working on repositories they already knew. In that specific setting, developers allowed to use then-current AI tools took 19% longer to complete tasks, despite believing that AI had made them faster. METR explicitly cautioned against generalizing the result to all developers or all software engineering tasks.
These findings are not necessarily contradictory.
AI can be extremely effective for one type of work and counterproductive for another. Generating boilerplate in an unfamiliar framework is fundamentally different from modifying a complex repository that an experienced developer already understands deeply.
Teams should therefore measure AI productivity in their own environment rather than assuming a universal productivity multiplier.
The relevant question is not how much code AI generates. It is whether cycle time, review effort, defect rates, rework, developer focus, and delivery outcomes improve.
Context Is Becoming Part of AI Infrastructure
As AI moves deeper into development workflows, teams eventually encounter a context problem.
A general-purpose model may understand Java, React, PostgreSQL, or Kubernetes, but it does not automatically understand why a particular company chose a specific architecture, which internal APIs should be used, what naming conventions apply, which services are deprecated, or which compliance rules affect a particular feature.
This is where mechanisms such as repository context, retrieval-augmented generation, internal knowledge bases, tool connections, and MCP become useful.
The supplied expert source distinguishes several mechanisms for extending AI into organizational knowledge, including MCP for connecting tools and data, RAG for retrieving relevant domain information, and fine-tuning approaches for shaping model behavior.
These mechanisms solve different problems and should not be treated as interchangeable.
A development agent that needs the current state of an issue tracker needs live access rather than model training. An assistant answering questions about internal architecture may benefit from retrieval over technical documentation. A model required to produce highly standardized output may need stronger behavioral constraints.
The architecture should therefore begin with the information problem rather than with a preferred AI technology.
Security Cannot Be Added After AI Adoption
AI-assisted development introduces security concerns at two different levels.
The first is the security of the software AI helps produce. Generated code can contain vulnerabilities, misuse APIs, introduce insecure dependencies, or implement security-sensitive logic incorrectly.
The second is the security of the AI development environment itself. Models and agents may receive proprietary source code, customer information, credentials, internal documentation, logs, infrastructure details, and other sensitive context.
NIST's Secure Software Development Framework has been extended with specific guidance for generative AI and AI systems, reinforcing the principle that AI-related security practices need to be incorporated throughout the software lifecycle rather than handled as a final review step.
Organizations therefore need explicit policies governing what information can be provided to external models, which AI tools are approved, how credentials are handled, what agents can access, and which actions require human authorization.
For organizations working with regulated information, sensitive intellectual property, or strict client confidentiality requirements, cloud AI may not always be appropriate for every workflow. Private deployment, restricted environments, or carefully controlled enterprise AI services may be necessary depending on the data involved.
The important point is that governance should follow the sensitivity of the information and the authority given to the AI, rather than being treated as a generic company-wide yes-or-no decision.
AI-Generated Code Still Needs a Secure Development Lifecycle
AI does not create an exception to normal software engineering practices.
Generated code should still pass automated tests, static analysis, dependency checks, security scanning, review, integration testing, and whatever quality gates apply to manually written code. In security-sensitive components, additional scrutiny may be appropriate precisely because the code was generated quickly.
This becomes particularly important when agents can generate substantial changes across multiple files. A large implementation may look coherent while containing a subtle incorrect assumption that propagates through the entire change.
One useful approach is to separate generation from validation wherever practical. The same agent that produced the implementation should not be treated as the only authority deciding whether that implementation is correct.
Independent tests, deterministic tooling, security scanners, CI checks, and human review provide different forms of evidence.
AI can participate in validation, but it should not become its own quality gate.
Observability Becomes Necessary for Agentic Development
Traditional software observability focuses on applications after deployment. Agentic development introduces another system that needs to be observable: the AI workflow itself.
When an agent spends several minutes completing a task, teams may need to understand which model calls occurred, which tools were invoked, how many retries happened, how many tokens were consumed, which resources were accessed, and where the process failed.
OpenTelemetry has already introduced GenAI semantic conventions intended to standardize telemetry for model interactions, including model information, token usage, tool calls, and related operations.
This becomes particularly valuable as AI workflows grow more complex.
Without telemetry, an agent that repeatedly calls an expensive model, enters a retry loop, or invokes an unnecessary tool may simply appear "slow." With observability, teams can identify where time and money are actually being spent.
The same information also contributes to governance because logs can help establish what an agent did, which systems it accessed, and why a particular development artifact exists.
AI Development Costs Need to Be Measured Too
Productivity gains do not automatically make an AI workflow economically efficient.
Coding assistants have subscription costs, while API-driven workflows introduce token and inference costs. Agents can perform several model calls for a single task, and long repository contexts can increase consumption substantially. RAG infrastructure, vector databases, model hosting, GPUs, observability, security controls, and engineering work required to maintain internal AI platforms add further costs.
The correct comparison is therefore not simply AI subscription cost against developer salary.
Teams need to consider whether AI reduces total effort per completed engineering outcome.
If an agent produces a feature in thirty minutes but an experienced engineer then spends several hours understanding and correcting it, the apparent acceleration may not translate into actual productivity.
Conversely, an agent that handles repetitive migrations, test generation, documentation updates, or issue investigation while an engineer performs higher-value work may provide substantial economic value even when inference itself is relatively expensive.
AI cost optimization should therefore be evaluated together with engineering throughput, review effort, rework, quality, and operational impact.
Avoid Turning AI Into a New Source of Technical Debt
One of the largest long-term risks of AI-assisted development is not obviously broken code. It is plausible code that works today but nobody properly understands.
When generation becomes inexpensive, developers can accept larger implementations than they would have written manually. If those changes are merged without understanding their architecture and assumptions, the repository gradually accumulates software that the team owns without fully comprehending.
This problem becomes more serious when the next modification is also delegated to AI. Each layer can build on assumptions introduced by earlier generated changes until the system becomes difficult for humans to reason about without the same tools that created it.
The result is a new form of technical dependency.
AI should therefore reduce the mechanical burden of engineering without removing the requirement that teams understand the systems they operate.
A Practical AI Development Workflow
The strongest AI-assisted workflows do not begin by giving an agent unrestricted access to the entire engineering environment. They expand AI responsibility progressively as the team develops confidence in specific use cases.
A reasonable starting point is assistance with low-risk, easily verifiable work such as explanations, boilerplate, documentation drafts, test scaffolding, and small refactors. Once these workflows become reliable, AI can receive broader repository context and participate in debugging, test generation, code review, and multi-file changes.
Agentic workflows can follow once appropriate engineering controls exist. At that stage, agents may investigate issues, modify branches, execute tests, or prepare pull requests, while permissions remain restricted and consequential actions continue to require approval.
Production access represents a much higher threshold. An agent capable of changing infrastructure, deploying software, accessing sensitive systems, or modifying production data should operate within explicit security boundaries, auditability requirements, and human approval mechanisms.
This progression allows the organization to increase AI autonomy only when its ability to verify and govern that autonomy increases as well.
Build Safer AI-Assisted Development Workflows with Us
Book a free call nowMeasure Outcomes Instead of AI Adoption
An organization can purchase AI licenses for every developer and still have no evidence that software delivery improved.
Adoption is not the objective.
A more useful evaluation examines whether developers complete appropriate tasks faster, whether pull requests spend less time waiting for changes, whether review effort changes, whether test coverage improves, whether escaped defects increase or decrease, whether documentation remains more current, and whether AI-generated changes create additional rework.
DORA's 2025 findings are particularly relevant because they frame AI as an amplifier rather than an independent transformation mechanism. A strong development environment with good tests, fast feedback, clear standards, modular architecture, and effective review is positioned to obtain more value from faster generation. A weak development system may simply accelerate the production of work that its existing processes cannot validate efficiently.
This makes AI adoption partly an engineering maturity problem.
Before asking how much work an agent can perform, teams should understand how quickly and reliably they can determine whether that work is correct.
The Developer's Role Is Moving Toward Intent, Context, and Verification
AI does not eliminate software engineering simply because it can produce software artifacts.
Someone still needs to understand what the product should do, translate ambiguous business requirements into technical decisions, evaluate architecture, determine acceptable tradeoffs, understand failure modes, protect sensitive information, and decide whether a generated implementation should become part of the production system.
What changes is where engineering time is spent.
Less time may be required for repetitive implementation, syntax lookup, boilerplate, routine test construction, documentation drafting, and mechanical repository work. More attention can then move toward system design, requirement clarification, integration, verification, security, performance, and technical decision-making.
This shift also creates a risk that should not be ignored. If developers stop implementing, debugging, and investigating systems themselves, some of the expertise required to recognize incorrect AI output may gradually weaken. The supplied expert article raises exactly this concern, warning that teams can become dependent on AI if engineers move entirely toward describing and reviewing work while losing direct familiarity with the underlying systems.
The sustainable model is therefore not maximum delegation.
It is selective delegation combined with retained engineering competence.
Conclusion
AI is already becoming part of software development, but the difference between productive adoption and expensive experimentation has relatively little to do with whether a company has access to the newest model.
The important questions concern workflow design.
Teams need to decide which tasks are sufficiently predictable to delegate, what context AI needs to perform them correctly, how generated work will be validated, what information models can access, which actions agents are permitted to perform, and where human approval remains mandatory.
Code assistants can accelerate implementation and learning. Repository-aware tools can reduce investigation time. AI-assisted testing and review can provide additional quality signals. Retrieval and connected tools can expose organizational knowledge to models, while coding agents can execute increasingly complete development workflows.
Each increase in capability, however, increases the importance of control.
Current evidence also suggests that AI productivity should not be taken for granted. Developers frequently report productivity improvements, but controlled studies and DORA research show that the effect depends heavily on the type of work and the surrounding engineering environment.
The objective should therefore not be to maximize the percentage of code written by AI.
A better objective is to reduce the amount of engineering time spent on mechanical work while preserving the human understanding, review, security, and architectural judgment required to build software that can actually be maintained.
The teams that achieve that balance will not simply write code faster. They will build a development system in which human engineers and AI each handle the work they are best equipped to perform.
