How Netflix, Uber & Instagram Scale High-Load Systems
When millions of people interact with a digital platform, even relatively small architectural inefficiencies can become significant operational problems. A database query that performs adequately under moderate traffic may overwhelm storage infrastructure when executed thousands of times per second. A service dependency that introduces a few milliseconds of additional latency can affect the performance of an entire request chain. A temporary infrastructure failure can propagate across multiple components when the system lacks effective isolation and recovery mechanisms.
Netflix, Uber, and Instagram encounter these challenges in different ways.
Netflix must deliver large volumes of video content while coordinating account management, recommendations, subscriptions, and playback services. Uber operates a real-time marketplace where location updates, trip requests, pricing, payments, and dispatch decisions interact continuously. Instagram processes enormous volumes of media, social interactions, and personalized recommendations while maintaining a responsive experience for users around the world.
The scale of these platforms provides valuable insight into how distributed systems evolve under sustained demand.
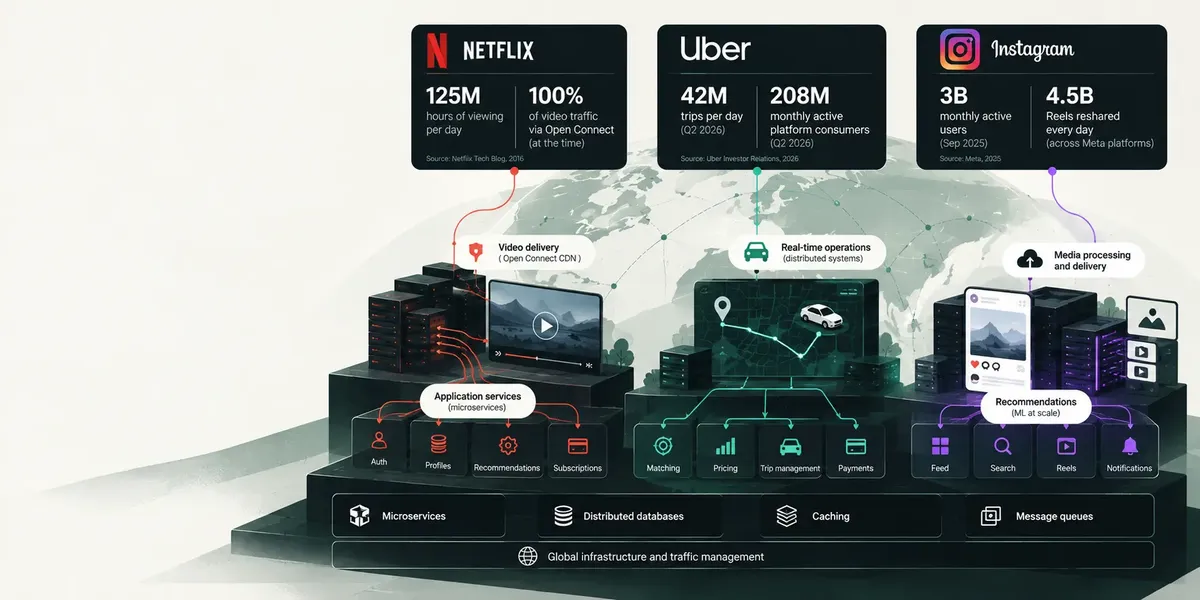
According to Uber's investor relations data, the platform handled approximately 42 million trips per day during the second quarter of 2026. Meanwhile, Meta reported that Instagram reached 3 billion monthly active users in September 2025.
These figures describe different workloads and cannot be directly compared as requests per second. However, they illustrate the operational scale at which architectural decisions become critical.
Understanding how these companies approach distributed systems can help engineering teams make better decisions about microservices, databases, infrastructure, and application scalability.
Why High-Load Architecture Becomes More Complex as Platforms Grow
At an early stage, many applications can operate successfully with a relatively simple architecture consisting of an application server, a relational database, and a small number of supporting services.
As traffic increases, the application begins to encounter limitations that are difficult to resolve through additional server capacity alone.
Different components experience different workloads. Authentication services may receive frequent requests but perform relatively little computation. Recommendation systems may require expensive processing and access to substantial datasets. Media delivery generates significant network traffic, while payment processing demands consistency, security, and reliable transaction handling.
These differences influence how individual components should scale.
A platform may need to increase recommendation-processing capacity without expanding its billing infrastructure. It may need to distribute frequently accessed data across multiple regions while keeping sensitive transactions within tightly controlled storage systems.
This is where high-load architecture becomes closely connected to service boundaries, data ownership, distributed communication, and workload-specific scaling.
Microservices can support this separation by allowing individual services to evolve and scale independently. Distributed databases make it possible to spread data and operations across multiple machines. Caching reduces repeated computation and storage access, while asynchronous processing allows systems to handle background workloads without extending the response time of user-facing requests.
The effectiveness of these techniques depends on how well they match actual traffic patterns.
Netflix, Uber, and Instagram provide three particularly useful examples because each platform has developed its architecture around a different dominant workload.
Netflix: Scaling Video Delivery and Distributed Services
Netflix operates a globally distributed streaming platform in which the delivery of video content must coexist with a large ecosystem of application services.
Its architecture has evolved to support geographically distributed users, personalized recommendations, subscription management, content discovery, and reliable playback across numerous device types.
Two aspects of Netflix's engineering approach are especially relevant to high-load systems: separating video delivery from application workloads and designing distributed services around independently scalable responsibilities.
How Netflix Separates Video Traffic From Application Services
Video streaming produces a very different infrastructure workload from a typical API request.
A request to retrieve account information may involve a relatively small amount of data. Streaming a high-resolution video requires sustained delivery of large media files over an extended period.
Attempting to serve both workloads through the same application infrastructure would create unnecessary competition for network and computing resources.
Netflix addressed this challenge by developing Open Connect, its own globally distributed content delivery network.
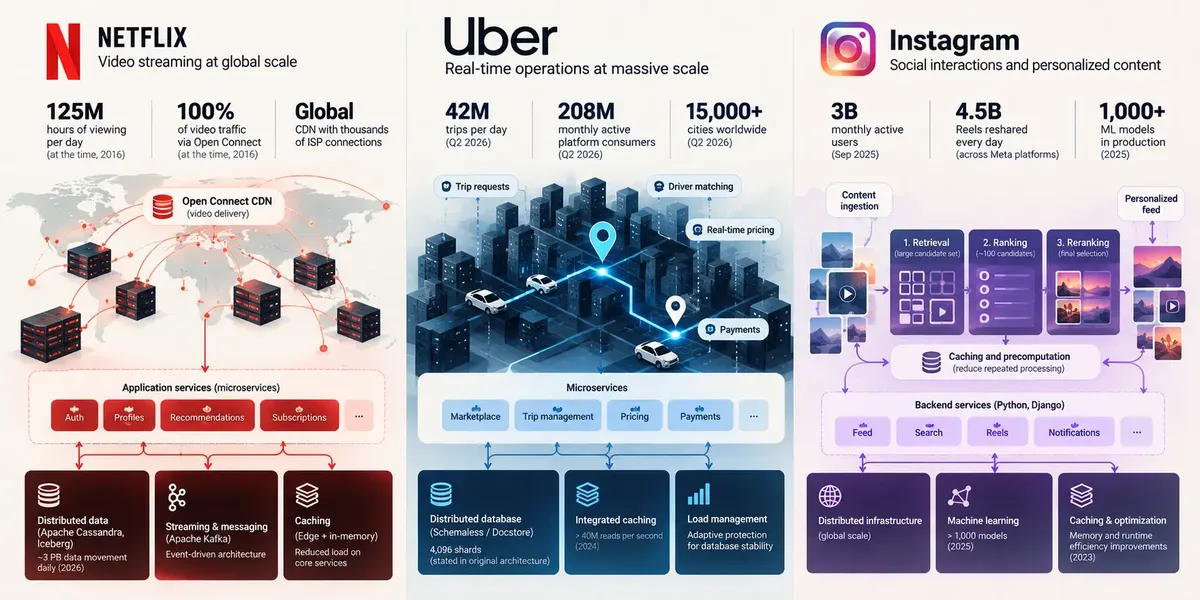
In a technical explanation published in 2016, Netflix reported that Open Connect delivered 100% of its video traffic, representing more than 125 million hours of viewing per day at that time. The company also stated that nearly 90% of its traffic was delivered through direct connections with internet service providers. These are historical figures describing the architecture at the time of publication, rather than current 2026 traffic measurements.
The underlying design remains instructive.
Frequently requested video content can be positioned close to users through distributed caching infrastructure. This reduces the distance data must travel and limits the amount of traffic passing through centralized systems.
For the application itself, the architectural benefit is substantial. Video delivery can scale according to bandwidth demand, while account services, recommendations, and other application components scale according to their own computational requirements.
This illustrates an important principle of distributed architecture: workloads with fundamentally different resource requirements benefit from independent scaling strategies.
Microservices and Independent Service Scaling
Netflix has long used distributed services to support different parts of its streaming platform.
A user's interaction with Netflix can involve authentication, profile management, content metadata, personalization, subscription verification, and playback-related operations.
These responsibilities create different patterns of computation, storage access, and availability requirements.
Separating them into services allows engineering teams to optimize individual workloads and manage their dependencies.
However, increasing the number of services also increases the complexity of communication between them.
A single user request may depend on several downstream systems. If one service becomes slow, the resulting delays can accumulate across the request chain. Under heavy traffic, repeated retries may increase pressure on already overloaded components.
This makes request timeouts, concurrency limits, dependency isolation, and fallback behavior essential considerations.
Netflix's engineering publications also demonstrate the importance of testing distributed services under controlled failure conditions.
Its Simone simulation framework, for example, was designed to help engineers reproduce service behaviors in a distributed environment. The architecture uses Apache Cassandra, Kafka, and replicated infrastructure to distribute simulation configurations while limiting their effect on normal production traffic.
The broader lesson is that microservices require operational mechanisms capable of detecting and containing failures across service boundaries.
Distributed Data Infrastructure at Netflix
Netflix's storage requirements extend well beyond video files.
The platform also manages information associated with members, billing, subscriptions, recommendations, and operational analytics.
In May 2026, Netflix published an engineering article explaining how its teams redesigned a large-scale data movement system built around Apache Cassandra and Apache Iceberg.
The previous implementation processed approximately 1,200 data movements per day, transferring around 3 petabytes of data between Cassandra and Iceberg.
As workloads grew, the system encountered problems involving large partitions, memory consumption, unnecessary intermediate tables, and dependencies between multiple services.
Netflix redesigned the architecture around reusable data-processing components, direct access to backups stored in Amazon S3, and more efficient transformations.
The engineering team reported that the redesigned system reduced execution costs and infrastructure requirements, with savings on the order of millions of US dollars.
This case demonstrates how high-load optimization can extend beyond serving live requests.
Large platforms also need scalable mechanisms for moving, transforming, analyzing, and recovering operational data.
The architecture supporting those activities can become a significant source of infrastructure cost and operational risk.
What Other Engineering Teams Can Learn From Netflix
Netflix demonstrates the value of separating infrastructure according to workload characteristics.
Media delivery, application requests, recommendation processing, and data movement place different demands on computing resources, storage systems, and networks.
Designing independent scaling mechanisms for these workloads allows infrastructure capacity to follow actual demand more closely.
The company's engineering experience also highlights the importance of service isolation, controlled failure testing, reusable infrastructure components, and cost-aware data processing.
For smaller platforms, these principles can be implemented with considerably simpler technology.
A conventional CDN, a well-designed application architecture, distributed caching, and reliable background processing may deliver many of the same benefits without requiring Netflix-scale infrastructure.
Uber: Distributed Systems Built Around Real-Time Operations
Uber presents a different high-load challenge.
Its platform coordinates real-time interactions between riders, drivers, couriers, restaurants, merchants, and numerous internal services.
A ride request can involve location processing, availability checks, matching, pricing, trip management, notifications, and payment operations.
These activities must remain coordinated even when individual components experience delays or failures.
According to Uber's second-quarter 2026 investor data, the company operated in more than 15,000 cities and reported approximately 208 million monthly active platform consumers.
Supporting this scale requires distributed infrastructure capable of processing large numbers of operations while preserving appropriate consistency guarantees.
How Uber's Microservices Architecture Supports Growth
Uber's engineering architecture evolved alongside the expansion of its services and geographic footprint.
As the platform grew, different business functions required increasingly specialized infrastructure.
Trip management, marketplace operations, payments, maps, and delivery services have distinct computational and storage requirements. Separating these responsibilities allows services to scale according to the traffic they receive.
However, distributed services introduce dependencies that must be managed carefully.
For example, a temporary slowdown in a database used by several services can affect multiple business functions simultaneously.
Uber's April 2026 engineering publication describes an infrastructure containing thousands of microservices supported by distributed databases operating across thousands of clusters.
Those databases store tens of petabytes of operational data and collectively serve tens of millions of requests per second.
At this scale, dependency management becomes one of the central challenges of microservices architecture.
How Uber Scales Distributed Databases
One of Uber's most important architectural decisions involved the evolution of its data storage infrastructure.
During its early growth, Uber relied on PostgreSQL for core trip data.
By 2014, rapid expansion had created storage and scalability limitations. The company needed a database architecture that could increase capacity as additional machines were introduced while maintaining high availability.
Uber developed Schemaless, a distributed datastore built on MySQL.
Its architecture separated request-processing workers from storage nodes, allowing these layers to scale independently.
Data was distributed across shards, with replication used to improve availability and protect against infrastructure failures.
In its original architecture, Uber described a typical configuration involving 4,096 shards, distributed across storage nodes with replicated copies.
This approach allowed storage capacity and request-processing capacity to grow independently.
Over time, Uber evolved its storage infrastructure further, introducing Docstore as a distributed transactional database.
Docstore supports horizontal scaling and provides stronger transactional capabilities for workloads requiring them.
The evolution from a single PostgreSQL instance to specialized distributed storage illustrates how database architecture often changes as the volume and characteristics of application data evolve.
Why Caching Is Essential to Uber's Performance
Even distributed databases have limits.
When applications repeatedly request the same information, processing every read through persistent storage creates unnecessary resource consumption.
Uber addressed this problem by introducing an integrated caching architecture for Docstore.
In February 2024, Uber published an engineering article explaining how the system served more than 40 million reads per second using its integrated cache.
The database stored tens of petabytes of information, while caching reduced the number of requests requiring access to the underlying storage infrastructure.
This is a useful example of how caching changes the economics of high-load systems.
A cache hit can avoid database processing, network communication with storage nodes, and potentially expensive disk access.
At millions of requests per second, relatively small improvements in cache efficiency can translate into substantial infrastructure savings.
However, caching also introduces consistency considerations.
Frequently changing information requires an appropriate invalidation strategy. Sensitive transactional data may need stricter consistency guarantees than content that can tolerate short periods of staleness.
Effective caching therefore depends on understanding how the application uses its data.
Protecting Databases From Traffic Overload
As Uber's infrastructure expanded, the company also encountered challenges associated with database overload.
A sudden increase in requests can exhaust available connections, CPU capacity, memory, or storage throughput.
When downstream services become slower, upstream services may retry failed requests. Those retries can increase the load on an already struggling component, creating a feedback loop that amplifies the original problem.
Uber's April 2026 engineering article describes the development of an intelligent load-management system for its distributed databases.
The architecture uses multiple signals to detect overload and manage incoming requests while protecting database stability and maintaining fairness between workloads.
Uber explains that static rate limits were insufficient for environments where requests differ substantially in resource consumption and latency characteristics.
The underlying principle applies to many high-load applications.
A system should understand the capacity of its dependencies and control incoming work before those dependencies become critically overloaded.
This can involve admission control, adaptive concurrency limits, request prioritization, backpressure, and controlled rejection of excess traffic.
These mechanisms become particularly valuable when several services share the same infrastructure.
What Other Engineering Teams Can Learn From Uber
Uber's architecture demonstrates how distributed systems must account for the relationship between real-time processing, data consistency, and dependency capacity.
Horizontal database scaling allows storage and throughput to grow. Caching reduces repeated work. Replication improves availability, while overload protection helps prevent local resource exhaustion from affecting the wider platform.
The company's experience also illustrates why database scaling requires architectural decisions beyond choosing a particular database engine.
Data partitioning, consistency guarantees, request routing, replication, and workload isolation all influence system behavior.
For applications handling payments, bookings, logistics, or other real-time operations, these considerations are often more important than maximizing raw requests per second.
Instagram: Scaling Social Interactions and Personalized Recommendations
Instagram operates at a scale where content delivery, social interactions, and machine learning must function together.
Users continuously upload media, browse feeds, watch videos, interact with accounts, and receive personalized recommendations.
The platform must process these activities while responding to changes in user behavior and maintaining consistent performance.
In September 2025, Meta reported that Instagram had reached 3 billion monthly active users and that Reels were being reshared more than 4.5 billion times per day across Meta platforms.
At this scale, recommendation infrastructure becomes a major part of application performance.
How Instagram Scales Its Python Backend
One particularly interesting aspect of Instagram's architecture is its continued use of Python.
Meta has publicly described its use of Python and Django within Instagram's frontend server infrastructure.
In an August 2023 engineering publication, Meta explained that Instagram uses a multi-process architecture combined with asynchronous execution to handle concurrent requests.
The engineering team also described how memory consumption can become a significant efficiency problem at large scale.
Instagram addressed part of this challenge through improvements to Python's object-management behavior, including work on immortal objects and shared memory.
This example is important because it demonstrates how runtime efficiency influences infrastructure capacity.
When an application operates across a large fleet of servers, reducing memory consumption per process can increase the number of requests supported by existing hardware.
Improvements at the programming-language or runtime level can therefore have substantial infrastructure implications.
For engineering teams, the lesson is that application-level optimization remains relevant even when horizontal scaling is available.
How Instagram's Recommendation System Handles Massive Data Volumes
Instagram's Explore feature must identify relevant content from an enormous pool of potential recommendations.
Evaluating every available item with an expensive machine learning model would require excessive computational resources.
Instagram addresses this through a multi-stage recommendation architecture.
According to Meta's engineering documentation, the system uses retrieval, initial ranking, more computationally intensive ranking, and final reranking to progressively narrow the candidate pool.
Lightweight models evaluate a relatively large number of candidates, while more expensive models process a smaller subset.
Meta describes an architecture in which the second-stage ranking model evaluates approximately 100 candidates selected by the earlier stage.
Caching and precomputation further reduce repeated processing.
This approach demonstrates a powerful scaling pattern: expensive computation becomes more manageable when the system first reduces the amount of data requiring detailed processing.
The same principle can be applied outside social media.
An ecommerce platform can narrow millions of products to a smaller candidate set before running sophisticated personalization models. A search engine can retrieve potentially relevant documents before applying expensive ranking algorithms. A fraud detection system can use lightweight rules to identify transactions requiring deeper analysis.
The architecture becomes more efficient when computational effort is allocated according to the value of each processing stage.
Scaling More Than 1,000 Machine Learning Models
Instagram's recommendation infrastructure has also evolved to support an increasing number of machine learning models.
In May 2025, Meta published an engineering article describing how Instagram scaled its recommendation infrastructure to support more than 1,000 ML models.
The challenge extended beyond running inference efficiently.
Engineering teams needed mechanisms for deploying models, estimating capacity requirements, validating performance, and managing infrastructure consumption.
Meta explained that introducing new models previously required extensive traffic simulation and manual capacity planning.
For a service requiring 500 replicas, engineers might gradually shift traffic in increments of approximately 20% while reallocating infrastructure from the previous deployment.
This process could become operationally expensive when repeated across numerous model launches.
The company subsequently improved its deployment and capacity-management processes to support faster iteration while maintaining reliability.
The case illustrates an increasingly important dimension of high-load architecture.
Modern platforms must scale both application traffic and the operational processes used to deploy new functionality.
A system capable of serving millions of requests can still become difficult to maintain if every deployment requires extensive manual coordination.
Caching and Precomputation in Recommendation Systems
Instagram's recommendation architecture relies heavily on avoiding unnecessary repeated computation.
For example, some machine learning operations can be performed in advance, while intermediate representations can be cached and reused.
This reduces the amount of processing required when a user requests recommendations.
The approach is especially valuable when some computations depend primarily on relatively stable content characteristics, while others depend on rapidly changing user behavior.
Separating these workloads allows the system to balance recommendation freshness with infrastructure efficiency.
Meta's documentation describes how caching and precomputation support the use of more sophisticated models without requiring every operation to be repeated for every request.
This principle extends to other high-load applications where expensive calculations can be reused across multiple requests.
What Other Engineering Teams Can Learn From Instagram
Instagram demonstrates how high-load optimization can operate at several architectural levels simultaneously.
Runtime improvements reduce resource consumption within application processes. Multi-stage processing limits expensive computation to the most relevant candidates. Caching and precomputation reduce repeated work, while capacity planning helps engineering teams deploy changes without destabilizing production infrastructure.
The company's experience also highlights the importance of matching scaling strategies to workload characteristics.
A recommendation service with expensive model inference requires different optimization techniques from an API that primarily retrieves records from a database.
What Netflix, Uber, and Instagram Have in Common
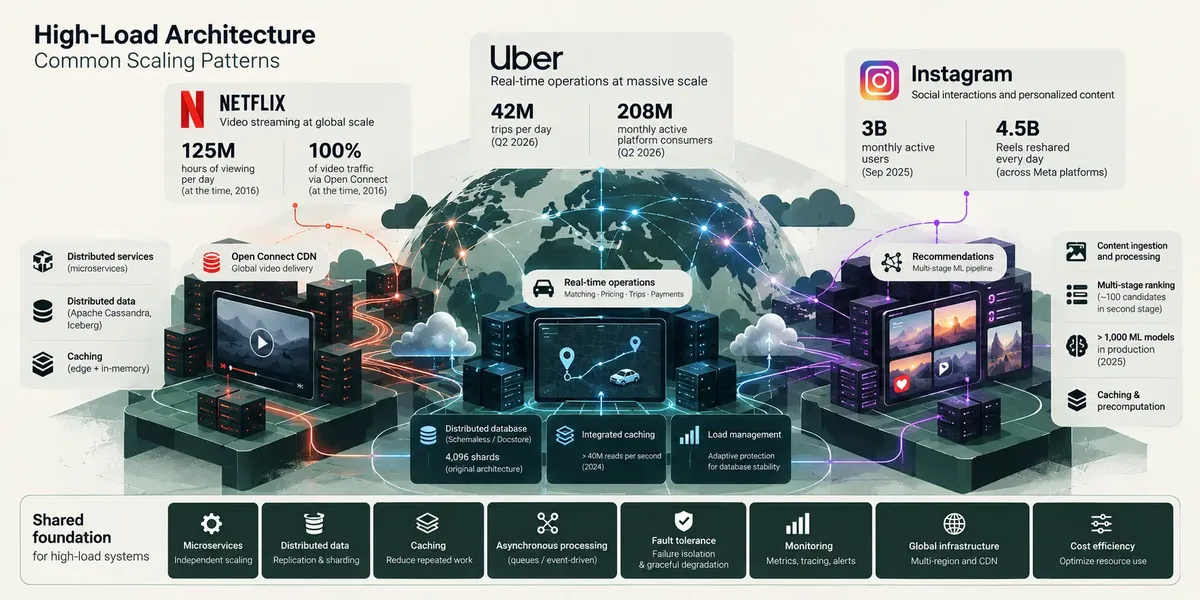
Although these platforms serve different markets, their published engineering architectures reveal several recurring patterns.
Independent Scaling of Different Workloads
All three companies have developed ways to separate workloads with different resource requirements.
Netflix separates large-scale video delivery from application services. Uber separates query processing from distributed storage and uses specialized infrastructure for real-time operations. Instagram separates recommendation retrieval from computationally expensive ranking stages.
This allows infrastructure capacity to be allocated more precisely.
The same approach can be applied to smaller applications by separating CPU-intensive background processing, database operations, API requests, and static content delivery.
Distributed Data and Replication
Distributed storage appears throughout the architectures of Netflix and Uber, while Meta operates large-scale data infrastructure supporting Instagram and its other products.
Replication improves resilience and supports geographically distributed operations, while partitioning allows datasets and workloads to grow beyond the capacity of individual machines.
However, distributing data introduces additional complexity involving consistency, synchronization, failure recovery, and operational management.
The appropriate architecture depends on the business requirements of the data being stored.
A social media recommendation cache can tolerate different consistency characteristics from a payment ledger or booking system.
Caching as a Core Architectural Component
Caching is one of the clearest recurring patterns.
Netflix uses geographically distributed caching to deliver video efficiently. Uber uses integrated caching to reduce database reads. Instagram uses caching and precomputation to improve recommendation performance.
These implementations operate at different levels of the technology stack, but they share the same objective: reducing unnecessary work in the most expensive parts of the system.
The benefits extend beyond response time.
Effective caching can reduce database infrastructure requirements, network traffic, computing costs, and the probability of overload during traffic spikes.
Workload Isolation and Failure Containment
As applications become distributed, failures can propagate through dependencies.
An overloaded database may delay several services. Those delays can trigger retries, which increase load and create additional failures.
Systems designed for high availability therefore require mechanisms that limit the impact of individual component failures.
Uber's adaptive load-management work provides a concrete example of protecting shared dependencies from excessive demand. Netflix's distributed service testing illustrates the importance of validating failure behavior before problems affect users.
These patterns connect directly to fault-tolerant systems, where redundancy, controlled retries, circuit breakers, and graceful degradation help maintain service availability during infrastructure problems.
Continuous Performance Measurement
Distributed systems generate complex performance relationships.
A slow user request may involve an overloaded application instance, inefficient database query, cache miss, network delay, or downstream service failure.
Understanding the cause requires visibility across the request path.
Metrics, distributed tracing, logs, and service-level indicators help engineering teams identify bottlenecks and understand how infrastructure behaves under changing workloads.
This is particularly important when traffic increases gradually and performance problems develop before they become visible to users.
Why Microservices Alone Do Not Guarantee Scalability
Microservices provide architectural flexibility, but their effectiveness depends on the infrastructure and operational practices surrounding them.
Splitting an application into independently deployed services can improve scalability when those services have clear responsibilities and different resource requirements.
However, excessive service fragmentation can increase network communication, deployment complexity, operational overhead, and the number of possible failure points.
A request that previously involved a function call within one application may require communication across several services.
Each additional network operation introduces latency and another potential failure condition.
Distributed transactions can also become more complicated when business operations span multiple independently managed databases.
These trade-offs are particularly important for growing SaaS platforms.
A modular monolith may provide sufficient separation for a product with moderate traffic and a relatively small engineering team. As particular workloads become difficult to scale independently, selected components can be extracted into separate services.
This evolutionary approach allows architecture to respond to demonstrated requirements.
Netflix, Uber, and Instagram have developed sophisticated distributed infrastructure over many years, supported by substantial engineering organizations.
Their current scale should therefore be understood as the result of ongoing architectural evolution rather than a template that every new application should reproduce.
How to Apply These Scaling Patterns to Your Own Application
The most useful lesson from large technology platforms is that scaling decisions should follow measurable workload characteristics.
An application experiencing database saturation may benefit from query optimization, indexing, caching, or read replicas before requiring database sharding.
A platform struggling with background processing may need asynchronous queues and independent workers.
A media-heavy application may benefit from CDN delivery and asset optimization.
A service experiencing unpredictable traffic spikes may require autoscaling, admission control, and more effective protection of downstream dependencies.
These decisions should be informed by production metrics and realistic load testing.
Understanding request distribution, latency percentiles, cache hit rates, database utilization, queue depth, and infrastructure costs makes it possible to identify where architectural changes will produce meaningful improvements.
For companies preparing to scale, this process often begins with an architectural assessment.
The objective is to identify current bottlenecks, understand the expected growth trajectory, and determine which components require independent scaling, stronger fault tolerance, or changes to data architecture.
A structured high-load engineering approach can help organizations make those decisions before infrastructure limitations begin affecting customers.
Build Infrastructure That Scales With Your Business
Contact our expertsThe Cost of Scaling Is Part of the Architecture
Large-scale engineering decisions have financial consequences.
Distributed databases require replication, storage, networking, and operational management. Microservices introduce deployment and observability overhead. Caching infrastructure consumes memory and computing resources, while geographically distributed systems can generate significant data transfer costs.
The most sophisticated architecture is not necessarily the most economical architecture for a particular workload.
Netflix's 2026 Cassandra data movement modernization provides a useful example. The company reduced infrastructure expenses by removing unnecessary intermediate processing and improving the efficiency of large-scale data transformations.
Similarly, Uber's integrated caching architecture demonstrates how reducing pressure on persistent storage can improve performance while changing the amount of infrastructure required to serve requests.
These cases illustrate why infrastructure efficiency should be considered alongside throughput and availability.
A system that scales technically but requires disproportionately increasing expenditure may eventually create business constraints.
For this reason, high-load infrastructure costs should be evaluated in relation to the business operations supported by the system.
Conclusion
Netflix, Uber, and Instagram demonstrate how large digital platforms develop different architectural solutions in response to their dominant workloads.
Netflix has invested heavily in geographically distributed content delivery, service resilience, and scalable data infrastructure. Uber has developed specialized distributed databases, integrated caching, and adaptive load management to support real-time operations. Instagram has focused extensively on efficient application execution, multi-stage recommendation processing, caching, and large-scale machine learning infrastructure.
Despite these differences, their engineering approaches share several important characteristics.
Workloads are separated according to their resource requirements. Data is distributed where necessary. Frequently repeated operations are optimized through caching and precomputation. Infrastructure is monitored continuously, and architectural changes are evaluated against performance, reliability, and operational cost.
For growing software products, these principles provide a practical foundation for making scaling decisions.
The appropriate implementation depends on traffic characteristics, business requirements, engineering resources, and the consequences of system failure.
A company serving thousands of users may need only a fraction of the infrastructure used by Netflix, Uber, or Instagram. Nevertheless, understanding the architectural decisions behind these platforms can help engineering teams anticipate bottlenecks, reduce unnecessary complexity, and design systems that remain reliable as demand increases.
