The Real Cost of High Load Systems: Infrastructure, Scaling, and Hidden Expenses
When teams begin estimating the cost of a high-load system, the conversation usually starts with visible infrastructure. They calculate how many application instances will be required, how powerful the database should be, whether Kubernetes is necessary, and how much additional capacity will be needed when traffic increases. These questions are important, but they represent only part of the financial model behind a large-scale application.
Infrastructure cost is ultimately determined by the interaction between architecture and workload behavior. A growing database may require read replicas to distribute queries. A CDN can reduce pressure on origin infrastructure while introducing another billing dimension. High availability requires redundant resources that may remain partially unused during normal operation. Monitoring generates ingestion and retention costs, while communication between regions or availability zones can produce significant network charges. Autoscaling can reduce idle capacity, but an inefficient scaling policy may also allocate additional resources in response to poorly optimized code, aggressive bots, retry storms, or malicious traffic.
Even something as ordinary as moving data between infrastructure components can become financially significant at scale. AWS recommends explicitly modeling data transfer because the resulting cost depends on where traffic originates, where it goes, and how much information moves between those locations.
This is why evaluating a high-load architecture exclusively through its monthly cloud invoice can be misleading. A system that saves several thousand dollars each month but becomes unavailable during peak traffic may ultimately cost the business much more than the infrastructure savings. At the opposite extreme, duplicating every component across several regions without a corresponding business requirement can consume substantial resources while delivering little additional value.
High-load cost optimization is therefore an engineering balance between performance, reliability, scalability, and financial efficiency. The objective is to understand which infrastructure expenses are necessary to deliver the product's requirements and which expenses exist because the architecture is performing unnecessary work.
High Load Changes the Economics of Infrastructure
A relatively small application can tolerate a surprising amount of technical inefficiency because the absolute number of operations remains limited. An API endpoint may perform several unnecessary database queries without creating an obvious performance problem. An oversized virtual machine may cost slightly more than necessary without attracting financial attention, while an unnecessarily large API response may waste bandwidth without materially affecting the overall infrastructure budget.
Once traffic reaches high-load levels, those inefficiencies are multiplied across millions or billions of operations. An endpoint that executes several unnecessary database queries no longer creates a small amount of wasted work when it receives millions of requests. The same principle applies throughout the architecture. Oversized instances become fleets of oversized instances, verbose application logs become terabytes of telemetry, ineffective caching generates repeated database operations, large payloads increase network traffic, and inefficient background processes consume compute capacity continuously.
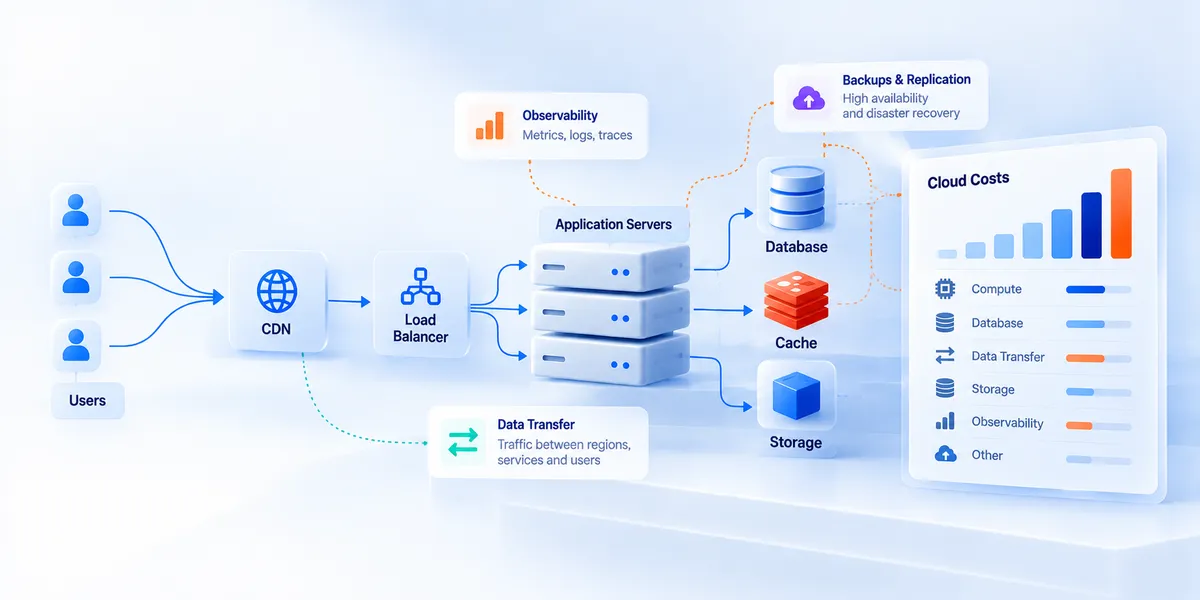
This multiplication effect is one of the reasons cost optimization needs to be treated as part of system architecture rather than as a financial exercise performed after the system has already been built. AWS recommends incorporating cost into architectural decisions and using workload metrics to determine appropriate resource types, sizes, and quantities. Microsoft similarly treats cost optimization as a continuous architectural discipline that must remain aligned with the functional and nonfunctional requirements of the workload.
Compute Is the Most Visible Cost, but It Is Only Part of the Problem
Compute is usually the easiest infrastructure expense to understand because it maps directly to resources that engineers can see. Application servers, containers, Kubernetes worker nodes, serverless functions, background workers, and processing clusters all require compute capacity, and growing traffic generally means that the application needs either larger machines or a greater number of instances.
Right-sizing is therefore one of the most obvious opportunities for optimization. If application instances consistently use only a small fraction of their available CPU and memory, the organization is paying for capacity that provides little practical value. Moving workloads to smaller instances or consolidating resources can reduce infrastructure spending without affecting user experience.
However, the opposite approach can create an equally serious problem. Infrastructure can be made artificially inexpensive by operating extremely close to maximum capacity, but doing so removes the headroom required to absorb traffic spikes, deployments, node failures, background processing, or unexpected demand. Microsoft explicitly identifies this tradeoff in its Well-Architected guidance, noting that underprovisioning and restrictive scaling can reduce cost while making workloads more vulnerable to sudden increases in demand.
The correct capacity level therefore cannot be determined by asking how small the servers can become. It needs to be determined by the amount of infrastructure required to satisfy performance and reliability objectives while maintaining enough headroom for realistic changes in workload behavior.
Overprovisioning Is Expensive Insurance
High-load systems are frequently overprovisioned for understandable reasons. Engineering teams do not want a major product launch to fail because there were too few application instances, nor do they want a database to exhaust its available connections during an important campaign. Maintaining additional capacity provides protection against uncertainty, and in many cases that protection is necessary.
Problems begin when temporary safety margins become permanent architecture. A platform designed to survive a theoretical peak of 50,000 requests per second may operate at a fraction of that volume during most of the year. If the entire infrastructure remains provisioned for maximum theoretical demand at all times, a large part of the budget is effectively paying for resources that remain idle.
Elastic infrastructure provides a way to reduce this gap by maintaining a reasonable baseline and adding resources as demand increases. AWS recommends using actual workload metrics when determining resource type, size, and quantity, including automated feedback mechanisms such as autoscaling.
Elasticity does not, however, eliminate the need for capacity planning. New application instances require time to start, databases cannot always expand at the same speed as stateless application servers, external services may enforce quotas, and connection pools or queues may become saturated before compute resources reach their limits. A cost-efficient high-load architecture therefore combines elastic capacity with a carefully selected baseline and scaling behavior that has been tested under realistic conditions.
Autoscaling Can Reduce Waste Without Fixing Inefficient Architecture
Autoscaling is one of the most useful mechanisms available for aligning compute spending with actual demand. When traffic decreases, unnecessary instances can be removed, while periods of higher activity can trigger additional capacity. In an appropriately designed system, this reduces the amount of infrastructure that remains idle simply because it might eventually be needed.
The limitation is that autoscaling responds to the workload it observes without determining whether that workload represents useful business activity. If a software defect causes every request to trigger an expensive background operation, CPU utilization increases and the infrastructure may correctly respond by provisioning additional instances. From the perspective of the scaling mechanism, the system is behaving exactly as designed, even though it is now spending more money to process unnecessary work.
Similar situations can occur when poorly configured clients generate retry storms, bots repeatedly access expensive endpoints, ineffective caching sends unnecessary traffic to databases, or malicious requests consume application resources. Autoscaling can provide additional capacity for all of these workloads, but it cannot determine whether they should have consumed infrastructure resources in the first place.
This creates a direct relationship between cost optimization, application performance, and security. Infrastructure should be capable of scaling legitimate demand while preventing inefficient or unwanted work from becoming an unlimited driver of cloud spending.
Optimize Your High-Load Infrastructure Without Sacrificing Performance or Reliability
Contact our expertsDatabase Costs Grow Together With Architectural Complexity
The cost of a high-load database is rarely limited to the price of a single database instance. As the workload grows, the system may require additional storage, read replicas, provisioned IOPS, backup retention, failover capacity, connection proxies, caches, search infrastructure, and eventually partitioning or sharding.
High availability introduces another layer of spending because some database resources exist primarily to protect the application against failure. A standby instance or replica may process relatively little production traffic during normal operation while remaining essential to the reliability model. From a simple utilization perspective, that resource may appear inefficient, but eliminating it changes the system's recovery capabilities and business risk.
Microsoft's mission-critical architecture guidance explicitly acknowledges that higher reliability creates financial cost because infrastructure often needs to be duplicated and distributed across availability zones or regions. At the same time, Microsoft warns against overengineering systems beyond the reliability requirements justified by the business.
Database cost therefore depends partly on questions that cannot be answered by engineering teams in isolation. The acceptable amount of downtime, potential data loss, recovery time, and impact of a regional failure all influence how much redundancy the architecture needs. A platform that processes critical financial transactions may justify a substantially different infrastructure model from an internal application that can tolerate several hours of downtime.
Data Transfer Is One of the Most Easily Overlooked Cloud Expenses
Compute resources and databases are visually prominent in architecture diagrams, while network traffic is often represented by simple arrows connecting components. Financially, however, those arrows can become significant once enough data starts moving through them.
Applications continuously transfer information between users, regions, availability zones, application services, storage systems, CDNs, external APIs, and other infrastructure components. Depending on the cloud provider and architecture, some of these traffic paths may generate transfer or processing charges.
AWS identifies data transfer modeling as an explicit cost optimization practice because pricing varies according to the source, destination, and volume of traffic. Traffic crossing regional boundaries can create additional charges, while certain networking components introduce processing fees on top of ordinary transfer costs.
NAT gateways provide a particularly useful example because AWS charges for both gateway availability and the volume of data processed. AWS therefore recommends considering alternatives such as VPC endpoints for supported services and paying attention to Availability Zone placement where unnecessary routing would create additional processing and transfer costs.
These architectural details can remain financially insignificant when traffic is low, which makes them easy to ignore during the early stages of product development. Once the same path begins carrying terabytes of data, however, a minor networking decision can become a recurring infrastructure expense.
CDN Architecture Can Improve Performance While Reducing Origin Costs
Content delivery networks are usually introduced because they reduce latency by serving content closer to users. Static assets and cacheable responses can be delivered from edge infrastructure instead of repeatedly traveling to the origin application, which improves response times for geographically distributed users.
The same architecture can also change the economics of the system. A successful cache hit can prevent an application request, database query, origin data transfer, or other downstream operation from occurring at all. Cloudflare's cost optimization guidance recommends increasing cache hit ratios where appropriate because cached responses reduce the amount of work that needs to reach downstream infrastructure.
AWS similarly describes CloudFront as a mechanism that can improve performance while reducing origin infrastructure and data transfer requirements.
This illustrates a broader principle that appears repeatedly in high-load cost optimization. The most valuable savings frequently come not from purchasing cheaper infrastructure, but from redesigning the request path so that unnecessary work never needs to be performed.
Caching Has an Infrastructure Cost of Its Own
Caching follows the same economic logic. A cached response can prevent repeated computation, reduce database traffic, and improve response latency simultaneously. At sufficiently high traffic volumes, an effective cache can reduce the amount of compute and database capacity required to support the application.
However, caching should not be treated as free infrastructure. Distributed caches consume memory, replicated caches require additional resources, and large clusters introduce their own monitoring, failover, and operational requirements. Poorly selected cache keys or inappropriate expiration policies can also produce large caches with disappointing hit ratios, leaving the organization paying for memory that rarely prevents meaningful downstream work.
The economic objective is therefore not to cache as much data as possible. It is to cache information when the cost of storing and maintaining the cached representation is lower than the repeated computation, retrieval, or network traffic that the cache eliminates.
At high load, understanding this relationship becomes increasingly important because both successful and unsuccessful caching strategies are multiplied across enormous request volumes.
Observability Develops Its Own Cost Curve at Scale
High-load systems produce large amounts of telemetry because engineers need enough visibility to understand how complex distributed infrastructure behaves. Metrics, application logs, distributed traces, security events, audit records, database telemetry, access logs, infrastructure metrics, and error reports may all be collected continuously.
This visibility is essential for operating production systems, but collecting, processing, indexing, transferring, and retaining telemetry consumes resources. As traffic increases, observability can become a meaningful part of the infrastructure budget rather than a negligible supporting service.
The correct response is not to disable monitoring in order to reduce spending, because doing so can create a much more expensive operational problem when incidents occur without enough information to diagnose them. Instead, teams need to determine which telemetry requires full fidelity, which data can be aggregated or sampled, and how long different classes of information need to remain immediately searchable.
Microsoft's cost optimization guidance similarly recommends governing metered monitoring ingestion and retention rather than assuming that unlimited telemetry collection is automatically beneficial.
This makes observability another example of the broader cost-performance tradeoff. Too little visibility creates operational risk, while indiscriminate collection can generate substantial recurring expenses without producing equivalent diagnostic value.
Redundancy Is an Intentional Cost of Reliability
Fault-tolerant systems contain infrastructure that can appear inefficient when everything is operating normally. Multiple application instances ensure that one server can disappear without taking the service offline. Database replicas preserve availability when the primary instance fails. Multiple availability zones reduce the probability that a single infrastructure event will interrupt the entire application, while cross-region architectures can duplicate substantial portions of the platform.
Some of this capacity may remain unused during normal operation, but that does not automatically make it wasteful. The economic value of redundancy comes from reducing the probability and duration of outages rather than maximizing utilization during ordinary conditions.
The important question is whether the level of redundancy corresponds to the business impact of failure. A payment platform processing critical transactions may justify substantial redundant infrastructure, whereas an internal reporting system that can tolerate temporary downtime may not require the same architecture.
Microsoft's Well-Architected guidance recommends evaluating the financial impact of disruption against the cost of preventing or recovering from that disruption. This provides a more useful foundation for reliability decisions than attempting either to maximize redundancy or minimize infrastructure spending independently.
Microservices Can Introduce an Infrastructure Tax
Microservices are frequently associated with scalability, but dividing an application into a larger number of independently deployed services does not automatically make the system faster, cheaper, or easier to scale. Each service may require its own runtime, deployment pipeline, monitoring, logging, secrets, permissions, health checks, networking configuration, and scaling policies.
Communication between services can also increase internal network traffic, while distributed tracing becomes increasingly important because a single user request may pass through several independent components before a response is returned. Organizations may subsequently introduce Kubernetes, API gateways, service meshes, message brokers, centralized observability systems, and additional operational tooling to manage the resulting environment.
All of these technologies can be justified when the system and organization genuinely require them, but they also create an infrastructure and operational cost that should be considered when choosing an architecture.
For some products, a modular monolith running across several application instances can support considerable traffic while remaining operationally simpler than a large microservice platform. Microsoft's architecture guidance similarly emphasizes selecting architectural styles according to the workload's reliability, security, cost, operational, and performance requirements rather than assuming that cloud applications require one particular pattern.
Managed Services May Cost More Per Resource and Less Overall
Direct infrastructure pricing can also create misleading comparisons. A self-managed database may appear cheaper than a managed database service, while self-managed Kubernetes or an open-source observability stack may look less expensive than their managed alternatives when only the provider invoice is considered.
The calculation changes when operational work is included. Infrastructure needs to be deployed, patched, monitored, secured, backed up, upgraded, and repaired when something fails. Engineers need to understand its behavior under load, respond to incidents, and maintain the automation surrounding it.
AWS recommends considering managed services, serverless technologies, containers, event-driven architecture, licensing, and organizational costs when selecting workload components rather than comparing resource prices in isolation.
The more meaningful metric is therefore total cost of ownership. A managed service that adds several thousand dollars to the monthly cloud invoice may still be economically preferable if it eliminates substantially more engineering and operational work.
Non-Production Infrastructure Can Quietly Become a Significant Expense
Production environments receive the most attention because they serve real users and generate visible business impact. Development, staging, QA, performance-testing, disaster recovery, preview, and experimental environments often receive considerably less financial scrutiny.
Together, however, these environments can consume a meaningful portion of the cloud budget. A staging environment rarely needs to operate at full production capacity continuously, while development infrastructure may not need to remain active overnight or during weekends. Temporary environments should have explicit lifecycle rules, and resources created for experiments should not remain indefinitely after those experiments have ended.
Optimization still requires restraint because reducing non-production infrastructure too aggressively can make it fundamentally different from production. When that happens, staging and performance environments may stop revealing the very scalability and reliability problems they are supposed to detect before deployment.
Microsoft's cost optimization checklist recommends aligning environment spending with the actual requirements of each environment, including its availability, operating hours, security, licensing, and purpose.
The goal is therefore not to make every non-production environment minimal, but to ensure that its cost reflects the function it actually performs.
Engineering Time Is a Hidden Infrastructure Expense
Cloud invoices are visible because every resource eventually appears as a financial line item. Engineering time is much more difficult to attribute, even though it can easily exceed the infrastructure savings generated by an optimization project.
A team can spend several weeks reducing the cost of a small infrastructure component and ultimately save less money than the engineering effort required to achieve that reduction. This problem becomes particularly common when optimization begins with technically interesting inefficiencies rather than with the largest financial drivers.
Effective optimization therefore starts with attribution. Teams need to understand which infrastructure components create the largest expenses, which products or customers generate those workloads, which endpoints consume disproportionate resources, which database operations dominate capacity, and which network paths create significant transfer charges.
AWS recommends establishing cost objectives, identifying workload components responsible for spending, and continuously monitoring them instead of treating cost optimization as a one-time cleanup activity.
Once the financial structure of the system is understood, engineering effort can be directed toward changes where the potential return justifies the development cost.
Reduce Infrastructure Costs While Keeping Your High-Load System Scalable
Ensure it with usThe Most Expensive Infrastructure Mistakes Often Begin Much Earlier
Cloud bills frequently expose architectural problems that were created long before the costs became noticeable. A database schema that does not support efficient access patterns may eventually require larger database instances. An application without an effective caching strategy can generate unnecessary reads, while synchronous workflows may keep compute resources occupied while waiting for operations that could have been handled asynchronously.
Similar patterns appear throughout the architecture. Large API responses consume unnecessary bandwidth, poorly designed retry mechanisms multiply traffic during failures, missing lifecycle policies allow storage to grow indefinitely, and excessive logging creates continuously increasing observability expenses. A platform designed around hypothetical future scale can also end up operating expensive distributed infrastructure years before its traffic actually requires that level of complexity.
These problems cannot usually be solved through cloud pricing discounts alone. Reserved capacity does not repair an inefficient query, a cheaper instance does not eliminate unnecessary data transfer, and autoscaling does not correct an endpoint that performs substantially more work than the business operation requires.
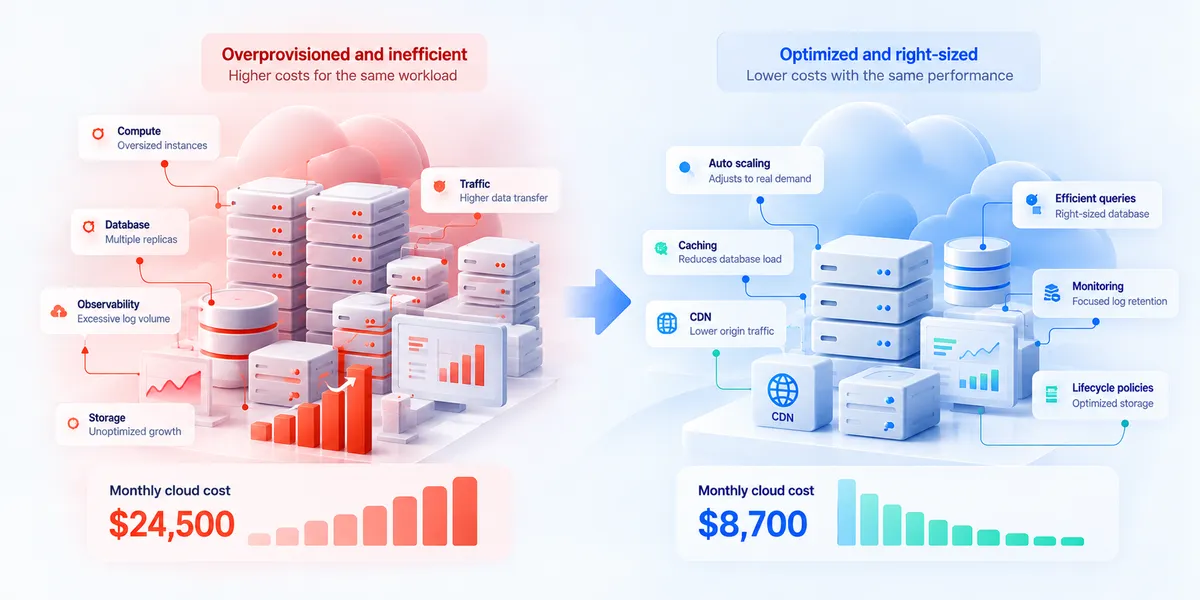
At a certain point, infrastructure cost optimization becomes software optimization because the amount of infrastructure a product needs is determined by the amount of useful and unnecessary work its software performs.
Cost Per Business Outcome Is More Useful Than the Monthly Cloud Bill
Absolute cloud spending provides important information for budgeting, but it does not necessarily reveal whether a high-load system is becoming more or less efficient.
Consider a platform whose monthly infrastructure cost grows from $20,000 to $30,000. Viewed in isolation, spending has increased by 50 percent. If the same platform has increased its workload from 100 million requests to 250 million requests during that period, however, the economic interpretation changes substantially. The infrastructure is more expensive in absolute terms while simultaneously processing each unit of workload at a lower cost.
This is why high-load teams benefit from connecting infrastructure expenses to business or workload outcomes. Depending on the product, the relevant measurement may be cost per transaction, active user, customer, order, million requests, gigabyte processed, AI inference, or successfully completed workflow.
AWS recommends evaluating efficiency through cost per business outcome and establishing optimization targets around those measurements rather than relying exclusively on total spending.
This distinction allows engineering and finance teams to separate healthy product growth from architectural inefficiency. Rising infrastructure spending is not automatically a problem when the business workload is growing even faster, while a stable cloud bill can still hide deteriorating efficiency if product usage is declining.
Performance Has a Price, but Poor Performance Has One Too
Cost and performance are often presented as competing objectives, but many technical improvements benefit both at the same time. An optimized database query can respond faster while requiring less database capacity. Effective caching can reduce latency and repeated computation. Smaller payloads improve frontend performance while decreasing network transfer, and more efficient application code allows the same compute resources to process a greater number of requests.
CDN architecture provides another example because serving content closer to users can improve latency while simultaneously reducing origin traffic. Removing unnecessary synchronous work can likewise improve throughput while decreasing the number of application instances required to maintain the same workload.
Performance optimization can therefore become cost optimization when it reduces the amount of infrastructure required to deliver a business operation.
The relationship is not unlimited, however. Reducing an already acceptable API response from 200 milliseconds to 100 milliseconds may require disproportionately expensive infrastructure without producing a meaningful improvement in user experience or business outcomes. At that point, additional performance is technically measurable but economically difficult to justify.
The appropriate target is therefore not maximum performance regardless of cost. It is sufficient performance for the actual requirements of the product at a cost the business can sustain as usage grows.
The Cost and Performance Balance Should Be Defined Through Measurable Objectives
The most reliable way to manage this tradeoff is to replace vague infrastructure goals with measurable requirements. An API should not simply be described as needing to be fast; it should have a latency objective appropriate to the user experience it supports. Availability requirements should describe how much downtime the business can tolerate rather than assuming that every service needs the highest possible availability. Capacity planning should be based on expected and peak workloads instead of an undefined requirement to support unlimited traffic.
The same reasoning applies to recovery objectives, telemetry retention, backup policies, and geographic redundancy. Once these requirements are explicit, infrastructure can be optimized within boundaries that are connected to actual business needs.
Azure's Well-Architected Framework treats cost optimization, reliability, security, operational excellence, and performance efficiency as interconnected architectural concerns. Improving one dimension without considering the others can therefore produce an architecture that looks efficient according to one metric while becoming significantly worse according to another.
A system that costs less but consistently violates its performance or availability objectives is not meaningfully cost-optimized. At the same time, an architecture that dramatically exceeds every requirement while maintaining large amounts of unnecessary capacity may also be economically inefficient.
The useful target lies between these extremes: the lowest sustainable cost that continues to satisfy the product's required business and technical outcomes.
High-Load Cost Optimization Should Be a Continuous Engineering Process
A practical optimization process begins by establishing an accurate baseline of how infrastructure spending is distributed across compute, databases, storage, networking, observability, third-party services, and different environments. Without that baseline, teams risk optimizing components that are visible but financially insignificant.
The next step is to connect those expenses to workload behavior. If traffic grows by 20 percent, infrastructure spending should be observed to determine whether it grows by less than 20 percent, approximately the same amount, or substantially more. Similar comparisons can be made against customer numbers, transactions, stored data, or whichever business metric most accurately represents the workload.
Once the relationship between usage and cost is understood, the largest drivers can be examined individually. Compute may be oversized, database queries may require optimization, cache hit ratios may be lower than expected, network traffic may cross expensive boundaries unnecessarily, telemetry retention may exceed operational requirements, or non-production infrastructure may remain active without providing corresponding value.
Only after those patterns are understood does it make sense to change instance sizes, purchasing models, caching strategies, scaling policies, data architectures, or service choices. Those changes then create a new baseline that needs to be measured again.
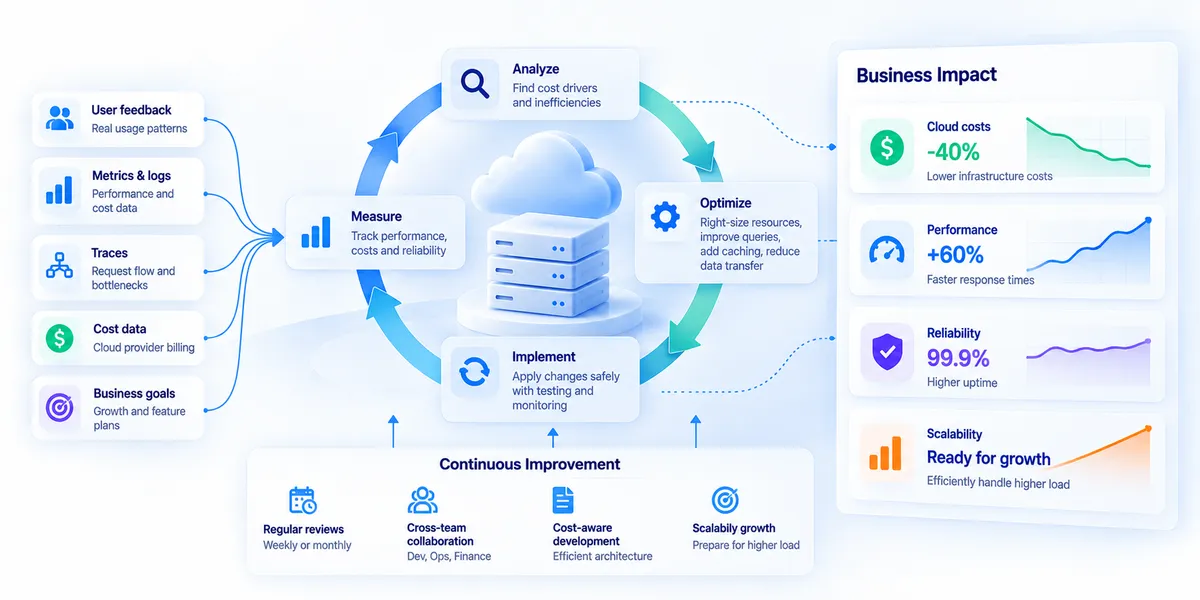
AWS describes cost optimization as a continuous lifecycle that includes regular architectural reviews and the removal of resources that are no longer required. This approach is particularly important for high-load systems because workload patterns, product requirements, cloud pricing, and architecture all continue changing over time.
Cheap Infrastructure Is Not the Same as Efficient Infrastructure
There is a version of cloud cost optimization in which every unused resource is interpreted as waste and every form of spare capacity becomes a target for reduction. Following that logic far enough can remove redundancy, eliminate capacity headroom, reduce backups, restrict scaling, shorten telemetry retention, and make testing environments significantly smaller than production.
The monthly invoice may improve, but the risk profile of the system changes with it.
Microsoft explicitly warns that aggressive cost reduction can reduce resiliency, recovery capability, security, and performance. Hard spending restrictions can also interfere with legitimate scaling when demand suddenly increases.
The objective should therefore be economically efficient infrastructure rather than simply inexpensive infrastructure. Efficient systems spend money where that spending creates measurable reliability, performance, security, or business value while continuously reducing resources consumed by unnecessary work.
Conclusion
The real cost of a high-load system cannot be calculated by adding together the prices of its servers. It emerges from every architectural decision and becomes more visible as those decisions are multiplied by scale.
Compute spending increases when applications require unnecessary capacity or instances are consistently oversized. Database costs grow through storage, replicas, backups, high availability, and increasingly demanding workloads. Network architecture introduces transfer and processing charges that may remain invisible until traffic becomes substantial. Observability becomes expensive because enormous request volumes produce enormous quantities of telemetry, while redundancy intentionally duplicates capacity in exchange for higher availability.
Distributed architectures can introduce additional infrastructure and operational complexity, and even mechanisms designed to reduce spending, such as autoscaling, can increase costs when they respond to inefficient or unwanted workloads.
At the same time, reducing infrastructure indiscriminately can make the system slower, less reliable, harder to operate, and more vulnerable to failure. Cost optimization therefore cannot be separated from performance engineering, reliability, security, and the business requirements the system exists to support.
The most useful financial question is not simply how the cloud bill can be made smaller. A more meaningful question is how much infrastructure is required to deliver one successful unit of business value and whether the architecture can deliver that unit more efficiently as the product grows.
When the cost per business outcome decreases while performance and reliability objectives continue to be satisfied, the architecture is becoming genuinely more efficient.
Build Cost-Efficient Infrastructure That Scales With Your Business Growth
Contact us